which AI should do your real work?
top score on the current test so far
Opus 5.5 74.25/100
5 AI setups have taken test pack 3.1.0, the same fixed set of tasks. one review of one run each, so small gaps can change.
- Opus 5.574.25
- Fable 5.269.43
- Gemini 4 Neon newest · 19 nov58.76
i give each AI the same real tasks from my own work, with the same time limit. i score the work, and if an AI gave any score, the result says which. i save the scores so they can’t change, then publish every result, its limits and any corrections.
find your job
which AI did best at each kind of job?
pick a job. you see every AI’s score on it, from test pack 3.1.0: 5 AI setups.
writingfounder writing from real source notes
best so farGemini 4 Neon52.8/100
- Gemini 4 Neonwith BuilderBench API harness52.8
- Opus 5.5with Claude51.4
- Fable 5.2with Claude39.8
- Gemini 4 Carbonwith BuilderBench API harness37.4
- Gemini 4 Hydrogenwith BuilderBench API harness27.4
task scores on test pack 3.1.0. one review of one run per AI, so small gaps can change. tap a row for the full result.
landing pageimproving a real product landing page
best so farOpus 5.570/100
- Opus 5.5with Claude70
- Gemini 4 Neonwith BuilderBench API harness58
- Fable 5.2with Claude40
- Gemini 4 Hydrogenwith BuilderBench API harness40
- Gemini 4 Carbonwith BuilderBench API harness38
task scores on test pack 3.1.0. one review of one run per AI, so small gaps can change. tap a row for the full result.
app lead magnetchoosing and building a small working app
best so farOpus 5.571/100
- Opus 5.5with Claude71
- Fable 5.2with Claude57
- Gemini 4 Carbonwith BuilderBench API harness49
- Gemini 4 Neonwith BuilderBench API harness45
- Gemini 4 Hydrogenwith BuilderBench API harness25
task scores on test pack 3.1.0. one review of one run per AI, so small gaps can change. tap a row for the full result.
video editinga finished video edit from raw footage
best so farOpus 5.578/100
- Opus 5.5with Claude78
- Fable 5.2with Claude76.67
- Gemini 4 Neonwith BuilderBench API harness65
- Gemini 4 Hydrogenwith BuilderBench API harness50
- Gemini 4 Carbonwith BuilderBench API harness36.33
task scores on test pack 3.1.0. one review of one run per AI, so small gaps can change. tap a row for the full result.
motionmotion graphics that explain an idea
best so farOpus 5.582/100
- Opus 5.5with Claude82
- Gemini 4 Hydrogenwith BuilderBench API harness70.5
- Fable 5.2with Claude68
- Gemini 4 Carbonwith BuilderBench API harness48.5
- Gemini 4 Neonwith BuilderBench API harness37
task scores on test pack 3.1.0. one review of one run per AI, so small gaps can change. tap a row for the full result.
thumbnailsvideo titles and thumbnails
best so farOpus 5.577.2/100
- Opus 5.5with Claude77.2
- Fable 5.2with Claude76.8
- Gemini 4 Hydrogenwith BuilderBench API harness69.6
- Gemini 4 Neonwith BuilderBench API harness65.4
- Gemini 4 Carbonwith BuilderBench API harness44.6
task scores on test pack 3.1.0. one review of one run per AI, so small gaps can change. tap a row for the full result.
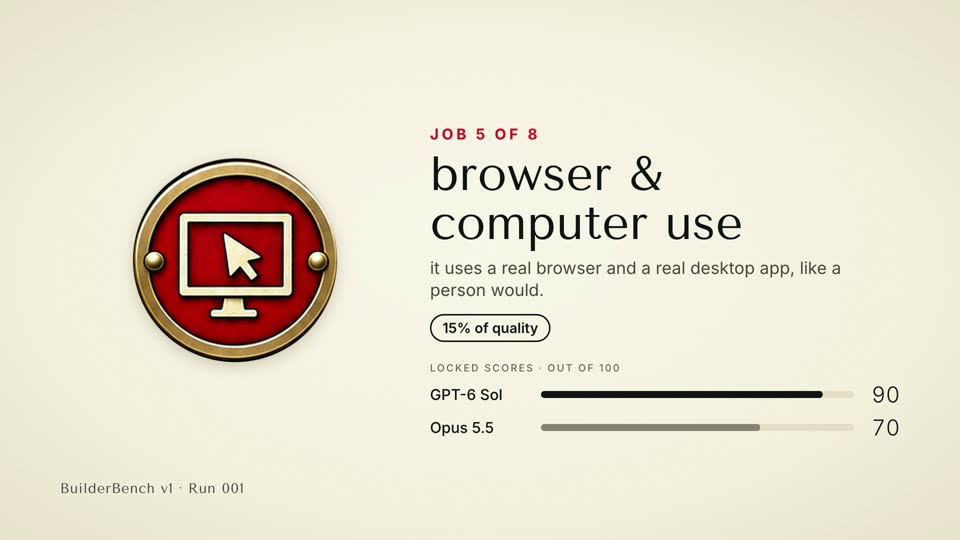
browser + computerusing a web browser and a computer by itself
best so farFable 5.275/100
- Fable 5.2with Claude75
- Opus 5.5with Claude72
- Gemini 4 Hydrogenwith BuilderBench API harnessrated by Claude, not Lennox56
- Gemini 4 Neonwith BuilderBench API harness55
- Gemini 4 Carbonwith BuilderBench API harness40
task scores on test pack 3.1.0. one review of one run per AI, so small gaps can change. tap a row for the full result.
researchsourced research that ends in a decision
best so farOpus 5.580/100
- Opus 5.5with Claude80
- Fable 5.2with Claude71
- Gemini 4 Hydrogenwith BuilderBench API harness70.5
- Gemini 4 Carbonwith BuilderBench API harness69.5
- Gemini 4 Neonwith BuilderBench API harness59.5
task scores on test pack 3.1.0. one review of one run per AI, so small gaps can change. tap a row for the full result.
automationfixing a broken technical workflow, with checks
best so farFable 5.289.33/100
- Fable 5.2with Claude89.33
- Opus 5.5with Claude89
- Gemini 4 Hydrogenwith BuilderBench API harnessrated by Claude, not Lennox86.67
- Gemini 4 Neonwith BuilderBench API harness78.33
- Gemini 4 Carbonwith BuilderBench API harness76
task scores on test pack 3.1.0. one review of one run per AI, so small gaps can change. tap a row for the full result.
founder conversationsadvice and planning conversations
best so farOpus 5.574.5/100
- Opus 5.5with Claude74.5
- Fable 5.2with Claude73.5
- Gemini 4 Neonwith BuilderBench API harness68
- Gemini 4 Carbonwith BuilderBench API harness61.5
- Gemini 4 Hydrogenwith BuilderBench API harnessrated by Claude, not Lennox61
task scores on test pack 3.1.0. one review of one run per AI, so small gaps can change. tap a row for the full result.
who runs this: me, Lennox Saint. the current tasks come from real work for Threadify, the business i co-founded, so they match my work. pick the jobs closest to yours. every task score is on each full result page.
words used on this page, in plain English
- test (pack)
- a fixed set of tasks. every AI in the same pack gets the same tasks, so scores only compare inside one pack.
- score out of 100
- 70% how good the finished work was (quality), 20% how little help it needed (autonomy), 10% useful extras nobody asked for (proactivity).
- harness
- the app or tool that runs the AI, like Codex or Claude Code. the score belongs to the AI and its harness together.
- cleared result
- a result Lennox checked and approved for publishing.
- owner review
- Lennox reviewed and scored the work. some checks are automated, and on one result he asked Claude to rate some parts for him. each result page says which. each result is one review of one run per AI.
- named or blind review
- named: Lennox could see which AI made the work. blind: the names were hidden until the scores were saved.
- partial review
- some of the work could not be fully checked. the result page says which parts.
- API estimate
- what the run would have cost at the AI company's listed prices. it is an estimate, not what was paid.
- reasoning (xhigh)
- how hard the AI was set to think. xhigh means extra high, the highest setting used.
every cleared score · out of 100
one run per setup. grouped by pack, highest first.
v1–v3: quality 70% · autonomy 20% · proactivity 10%. different packs are different tests, so there is no overall winner.
why you’d care: a score is how good the finished work was (70%), how little hand-holding it needed (20%), and whether it caught things i didn’t ask for (10%). higher means less fixing after the AI hands the job back.
pack 3.1.05 setups
- Opus 5.574.25/100quality 73.79, autonomy 73, proactivity 80.
- Fable 5.269.43/100quality 65.34, autonomy 77, proactivity 83.
- Gemini 4 Neonnewest58.76/100quality 57.65, autonomy 60, proactivity 64.
- Gemini 4 Hydrogen51.11/100quality 51.59, autonomy 50, proactivity 50.
- Gemini 4 Carbon49.04/100quality 49.48, autonomy 48, proactivity 48.
pack 3.0.08 setups
- Sonnet 5.548.98/100quality 51.40, autonomy 40, proactivity 50.
- GPT-6.1 Terra48.88/100quality 46.97, autonomy 54, proactivity 52.
- Kimi K3.1 Pro46.68/100quality 46.69, autonomy 50, proactivity 40.
- Gemini 4 Argon45.38/100quality 39.12, autonomy 60, proactivity 60.
- GPT-6 Luna44.58/100quality 45.12, autonomy 40, proactivity 50.
- GPT-6.1 Sol41.75/100quality 41.07, autonomy 30, proactivity 70.
- Muse Wonder Full39.91/100quality 37.73, autonomy 45, proactivity 45.
- Haiku 5.539.18/100quality 43.11, autonomy 30, proactivity 30.
pack 2.0.01 setup so far
pack 1.0.02 setups

packs 3.0.0 and 3.1.0
latest cleared result: 19 November 2026
the current cohort
ten real jobs built around Threadify.
v3 uses useful Threadify source material. the landing-page task improves the current public page as a benchmark preview. it does not replace production. the new app task makes each setup choose and build a working Threadify-adjacent lead magnet.
the build window is four hours. native live sessions are timed and recorded separately from the build window. 13 setups have a cleared v3 score so far, across packs 3.0.0 and 3.1.0. pack 3.1.0 asks for the same work in the words i really use when i prompt. its scores don’t compare with pack 3.0.0.
see all ten taskshow it works
four rules. no exceptions.
BuilderBench v1 
real jobs, not puzzles.
a frozen pack of work i actually do: writing, landing pages, browser jobs, workflow fixes.
from LAB 0009 
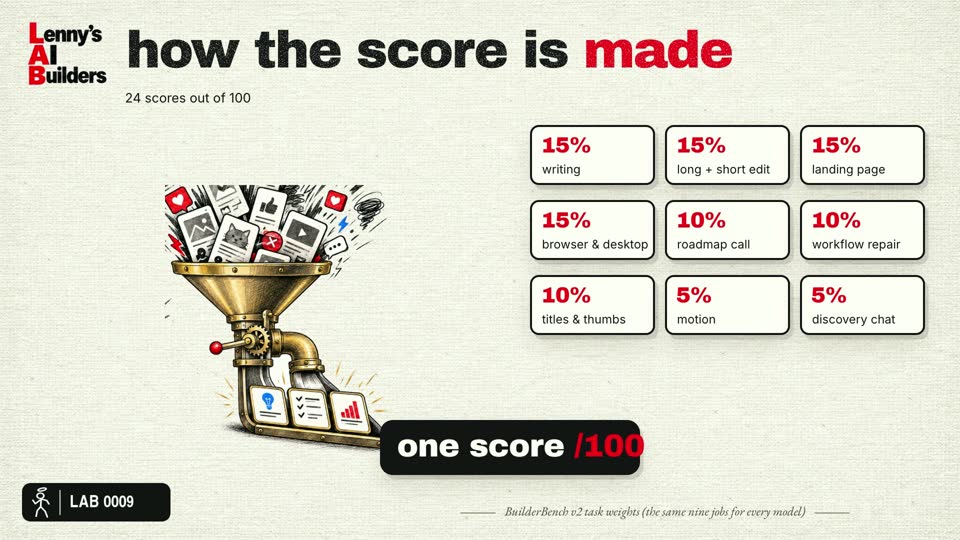
every job is weighted.
each job counts for a set share. the scores roll up into one number out of 100.
from LAB 0009 
reviewed. then locked.
named review is the default. a blind comparison hides two or more setups until the scores lock.
from LAB 0009 
costs and mistakes go public too.
every score, each model's API rates, the run estimate, the limits and any correction. dated.
the point: your work is the benchmark.
steal the method. score the AI on your own jobs.
read the full methodwhat this doesn’t prove
- each score is one owner's review of one run per setup. it is not a universal model ranking.
- a score belongs to the full setup: model, harness, tools and settings.
- different task packs are different tests. scores only compare inside one pack.
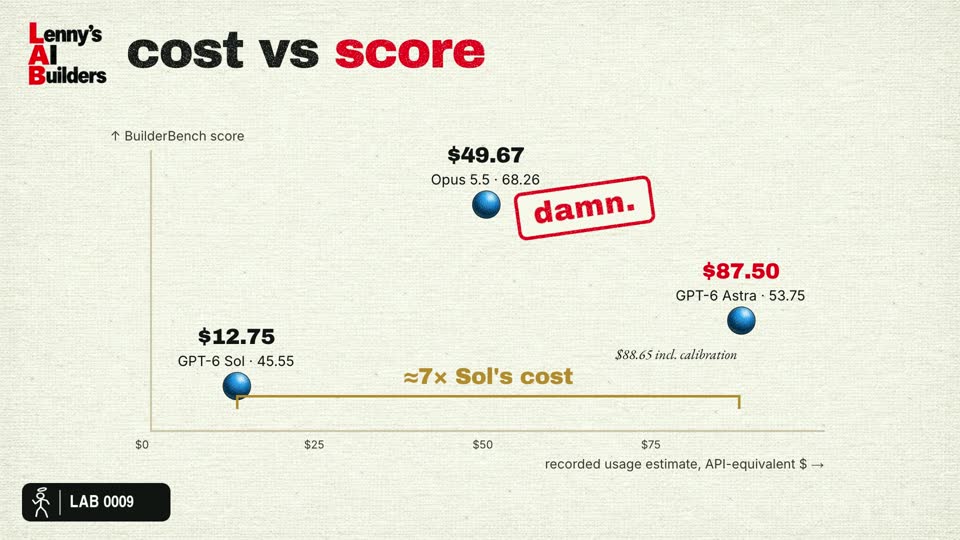
- costs are API-equivalent estimates with stated coverage, not bills. actual spend stays unknown unless it was receipted.
- API rates are a dated snapshot from the provider's own page. they are not the cost of a run.
- not every run was blind. each result says how it was reviewed.
- every result page lists its own limits, review scope and any correction.
how the scoring works
each setup gets the same frozen pack and the same four-hour build window. native sessions are timed separately. named review is the default: the model name shows. a blind comparison is something i ask for when two or more models run together, and it hides the names until the scores lock. v1–v3 weigh quality 70%, autonomy 20% and proactivity 10%. a later v4 pack will use 90/5/5. old scores are never recalculated.
read the full methodthe receipts
cleared results
grouped by task pack. different packs don’t compare.
pack 3.1.0
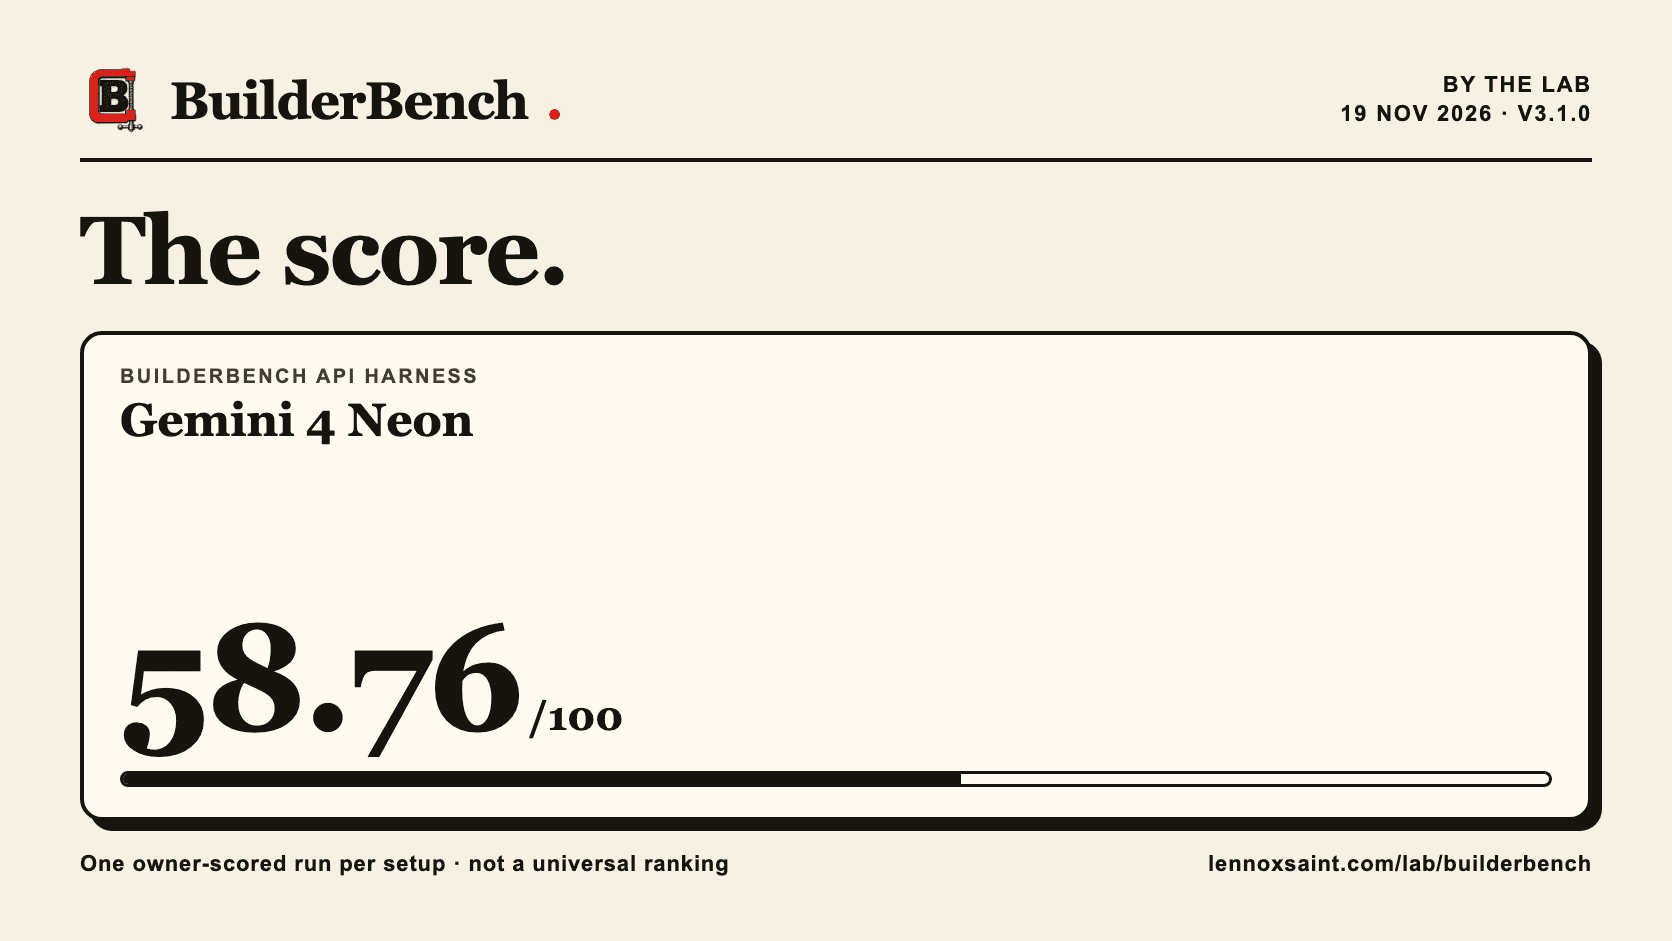 BuilderBench v3: Gemini 4 Neon19 November 2026 · Gemini 4 Neon 58.76owner-finalized partial personal review, with 3 of 28 ratings made by the bench's conductor (claude opus 5.5) and disclosed
 BuilderBench v3: Gemini 4 Hydrogen12 November 2026 · Gemini 4 Hydrogen 51.11owner review, with 7 of 28 ratings made by claude and disclosed
 BuilderBench v3: Gemini 4 Carbon11 November 2026 · Gemini 4 Carbon 49.04owner-finalized partial personal assessment
 BuilderBench v3: Fable 5.2 and Opus 5.510 November 2026 · Opus 5.5 74.25 · Fable 5.2 69.43owner-finalized partial personal assessment
pack 3.0.0
 BuilderBench v3: GPT-6.1 Terra and Kimi K3.1 Pro27 October 2026 · GPT-6.1 Terra 48.88 · Kimi K3.1 Pro 46.68owner-finalized partial personal review
 BuilderBench v3: Gemini 4 Argon and Muse Wonder Full14 October 2026 · Gemini 4 Argon 45.38 · Muse Wonder Full 39.91owner-finalized partial personal review
 BuilderBench v3: GPT-6 Luna and Haiku 5.58 October 2026 · GPT-6 Luna 44.58 · Haiku 5.5 39.18owner-finalized partial personal assessmentincludes a dated correction receipt
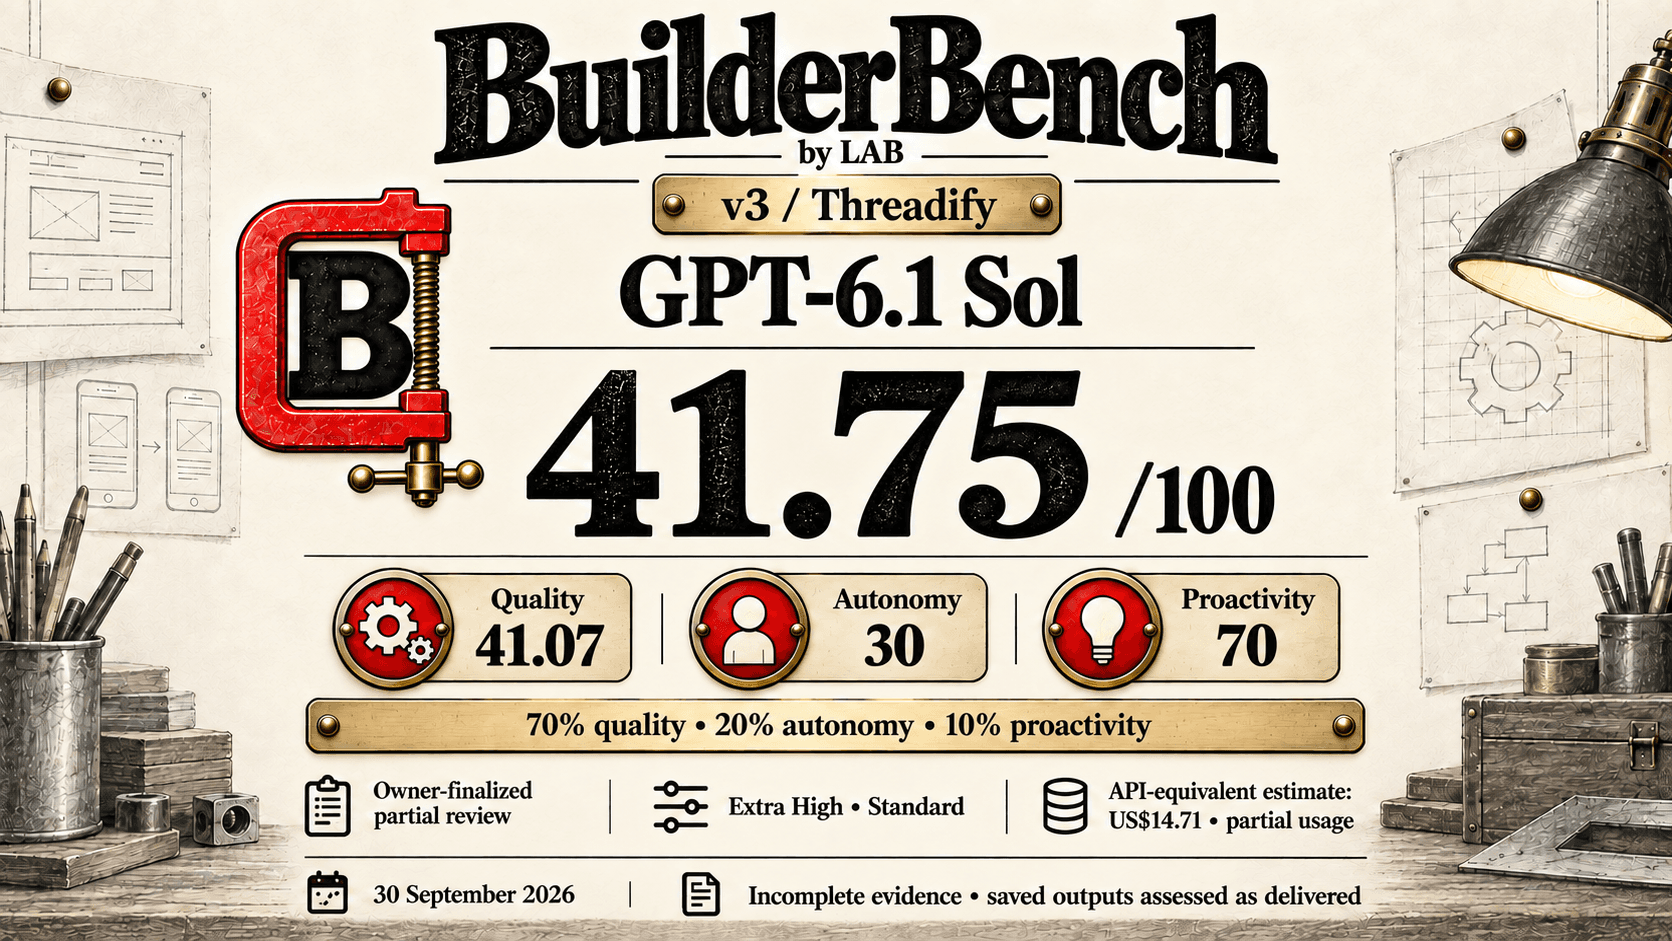 BuilderBench v3: GPT-6.1 Sol with Codex30 September 2026 · GPT-6.1 Sol 41.75owner-finalized partial personal assessment
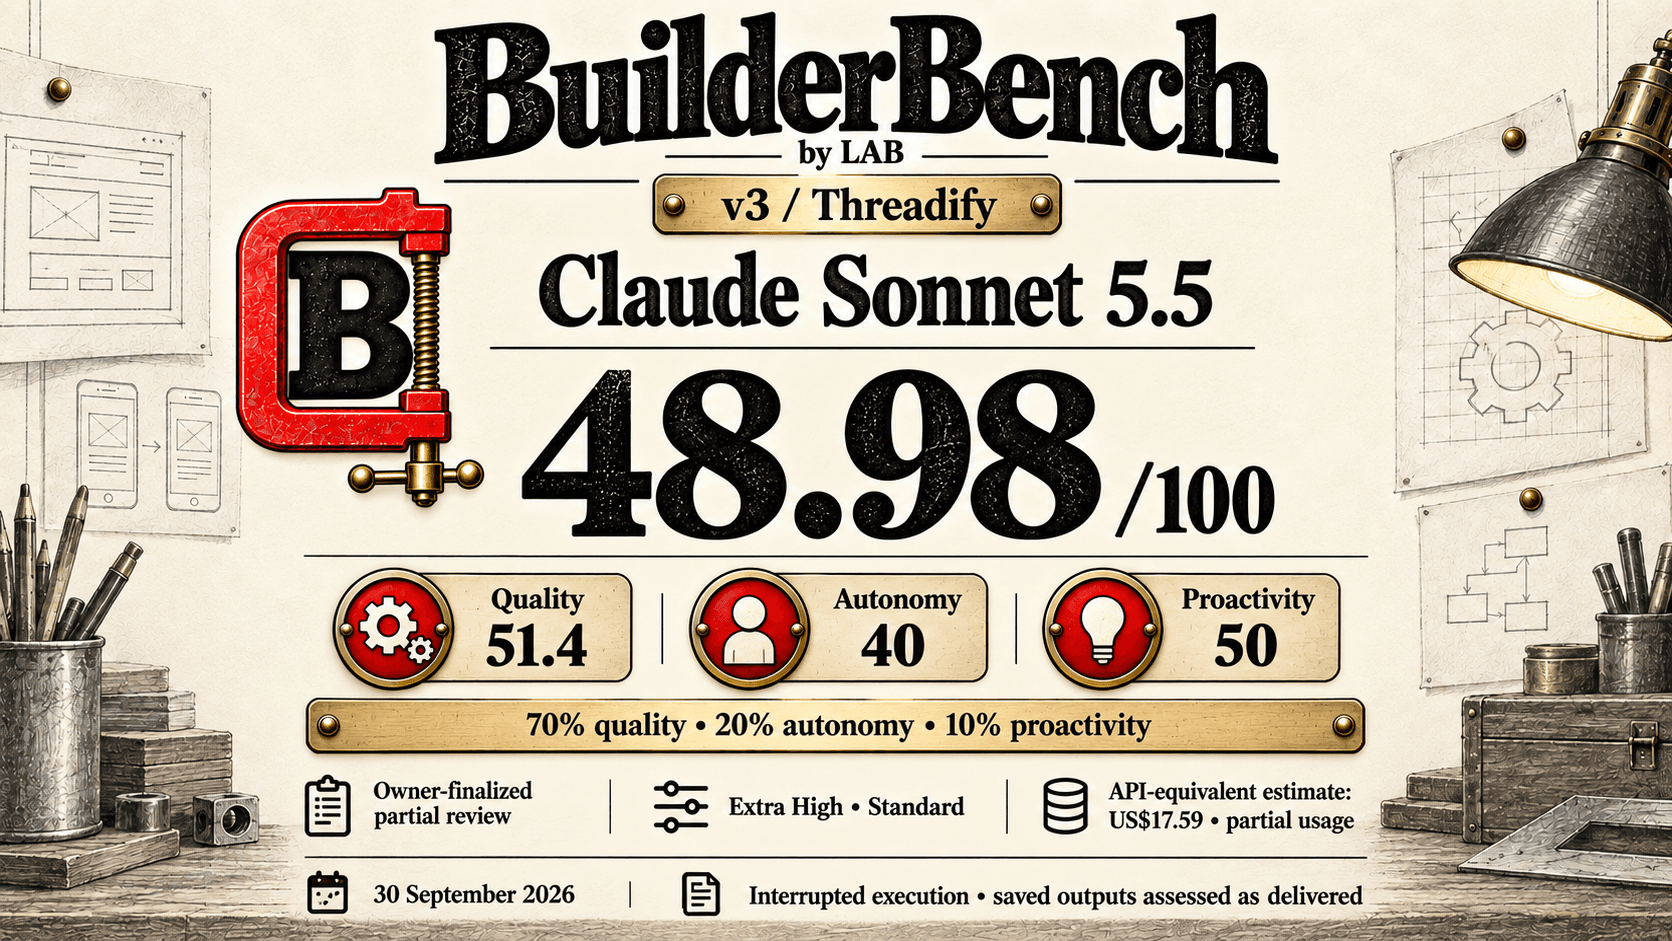 BuilderBench v3: Sonnet 5.5 with Claude29 September 2026 · Sonnet 5.5 48.98owner-finalized partial personal assessmentincludes a dated correction receipt
changelog
every change, dated. corrections get their own line.
new resultlogged · v3BuilderBench v3: Gemini 4 Neon
Gemini 4 Neon with BuilderBench API harness scored 58.76. One owner-finalized partial personal review of one Gemini 4 Neon run on the v3.1.0 pack. 25 of 28 ratings are the owner's own; the other 3 were made by the bench's conductor (Claude Opus 5.5) and are named below. This is not a universal model ranking or a statistical claim.
open: builderBench v3: Gemini 4 Neonnew resultlogged · v3v3 result: Gemini 4 Hydrogen 51.11 on pack 3.1.0
Gemini 4 Hydrogen with the BuilderBench API harness scored 51.11 on pack 3.1.0, in a run dated 12 November 2026. It compares only with other pack 3.1.0 results. One run, one review, locked on 15 November 2026. 21 of 28 ratings are the owner's. The bench's conductor (Claude Opus 5.5) scored the 3 automation outputs, and Claude rated the 4 live sessions on the owner's instruction, from the session logs and his earlier ratings. The cost is a partial estimate: 277 of 283 saved records are priced. Not a ranking.
open: v3 result: Gemini 4 Hydrogen 51.11 on pack 3.1.0new resultlogged · v3v3 result: Opus 5.5 74.25 and Fable 5.2 69.43 on pack 3.1.0
Opus 5.5 scored 74.25 and Fable 5.2 scored 69.43 on pack 3.1.0, both in Claude, in a run dated 10 November 2026. Opus 5.5 leads by 4.82 points. Owner-finalized partial personal assessment of one run each, rated blind as Candidate A and Candidate B. A usage limit cut off Fable 5.2's revision round on six build tasks, so both setups are scored on first-round work for those six. The computer-use session was not run; the computer task counts the browser session only. Both ran on a Claude Max subscription. The API-equivalent estimates are partial and do not compare like for like. Not a ranking.
open: v3 result: Opus 5.5 74.25 and Fable 5.2 69.43 on pack 3.1.0
show 19 older entries
new resultlogged · v3v3 result: Gemini 4 Carbon 49.04 on pack 3.1.0
Gemini 4 Carbon with the BuilderBench API harness scored 49.04 on pack 3.1.0, in a run dated 11 November 2026. It compares only with other pack 3.1.0 results, not with pack 3.0.0 scores. Owner-finalized partial personal assessment of one run, locked on 12 November 2026. The runner failed and the run hit Google timeouts and per-task deadlines, so some revisions and deliverables are missing. Missing work was not scored as zero; the owner scored what was delivered. The cost is a partial estimate: 112 of 123 saved records are priced. Not a ranking.
open: v3 result: Gemini 4 Carbon 49.04 on pack 3.1.0new resultlogged · v3BuilderBench v3: GPT-6.1 Terra and Kimi K3.1 Pro
GPT-6.1 Terra with Codex scored 48.88. Kimi K3.1 Pro with BuilderBench API harness (OpenRouter) scored 46.68. One owner-finalized partial personal review of one GPT-6.1 Terra and Kimi K3.1 Pro run on the v3.0.0 pack. This is not a universal model ranking or a statistical claim.
open: builderBench v3: GPT-6.1 Terra and Kimi K3.1 Promethodlogged · v3.1v3.1 plan: the tasks are asked the way Lennox asks
From pack 3.1.0, every task brief, revision and curveball is worded the way Lennox actually prompts Codex and Claude: the outcome first, exact counts, "make sure" for the checks, one blunt line for the limits, and curveballs that arrive as "also" or "by the way". The style comes from 1,334 messages he typed himself across his local Codex and Claude Code sessions. Only patterns were kept, never the messages. The work, files, checks, weights and rules are the same as 3.0.0. A model that only does well on spec-shaped prompts should not win a benchmark about his real work. 3.0.0 scores do not change, and 3.1 scores can't be compared with them. No 3.1 run has started.
open: v3.1 plan: the tasks are asked the way Lennox asksmethodlogged · v4v4 plan: the writing tests use the real templates
From pack v4, the X article, Threads post and Threads thread follow the same templates Lennox uses for real: his X article skill, his listicle plug template and Threadify's long-form thread template. The YouTube script follows the shape of his Threadify proof loops videos. A benchmark should test the real job, not a task made up in a vacuum. The templates stay private. v3 scores do not change, and v4 scores can't be compared with v3. No v4 run has started.
open: v4 plan: the writing tests use the real templatesnew resultlogged · v3v3 result: Gemini 4 Argon 45.38, Muse Wonder Full 39.91
Gemini 4 Argon with the BuilderBench API harness scored 45.38 and Muse Wonder Full with Muse Code scored 39.91 on pack 3.0.0. Argon leads this assessment by 5.47 points. Owner-finalized partial personal review of one run per setup. Not equal conditions: Extra High was requested but Argon ran on High, the two used different tools, a storage problem interrupted the build window, and the operator logs leaked identity clues. 3 of 4 native recordings have gaps. Argon's cost is a partial estimate; Muse Wonder Full's is unknown. Not a ranking.
open: v3 result: Gemini 4 Argon 45.38, Muse Wonder Full 39.91correctionlogged · v3correction after release: result graphic labels
The Luna and Haiku result graphic printed "candidate A" and "candidate B" under the model names, and a stray dash after "extra high". Both were taken out. Every score, price and caveat is unchanged.
open: correction after release: result graphic labelsnew resultlogged · v3v3 result: GPT-6 Luna 44.58, Haiku 5.5 39.18
GPT-6 Luna with Codex scored 44.58 and Haiku 5.5 with Claude scored 39.18 on pack 3.0.0. Luna leads this assessment by 5.40 points. Owner-finalized partial personal assessment of one run per setup; the original execution, native recordings and continuous review are incomplete, and the limits are on the page. Not a ranking.
open: v3 result: GPT-6 Luna 44.58, Haiku 5.5 39.18methodlogged · v3how runs work now: named by default, separate native ratings, API prices on every result
new runs keep ten task families, 70% quality, 20% autonomy and 10% proactivity, a four-hour build window and separately timed native sessions. named review is the default. a blind comparison is requested when two or more models run together. task 9 is conductor-scored with evidence. other owner ratings stay blank until supplied. future lead magnets get one owner rating for look and feel. the browser and computer prompts are now open demonstrations, and the computer one excludes browsers. each rating has its own help text. every result shows each model's official API rates, apart from the run estimate and the actual bill. older runs keep their frozen task versions and rubrics.
open: how runs work now: named by default, separate native ratings, API prices on every resultcorrectionlogged · v3Sonnet 5.5 v3 graphic date
The Sonnet 5.5 v3 result graphic shows 30 September 2026. That is the day the partial review was finalized. The run itself was on 29 September 2026, as the result page says. Scores, costs and limits are unchanged.
open: sonnet 5.5 v3 graphic datenew resultlogged · v3GPT-6.1 Sol v3 result is public
GPT-6.1 Sol with Codex scored 41.75 on pack 3.0.0. Owner-finalized partial personal assessment; independent checks and native recordings did not finish, and the limits are on the page.
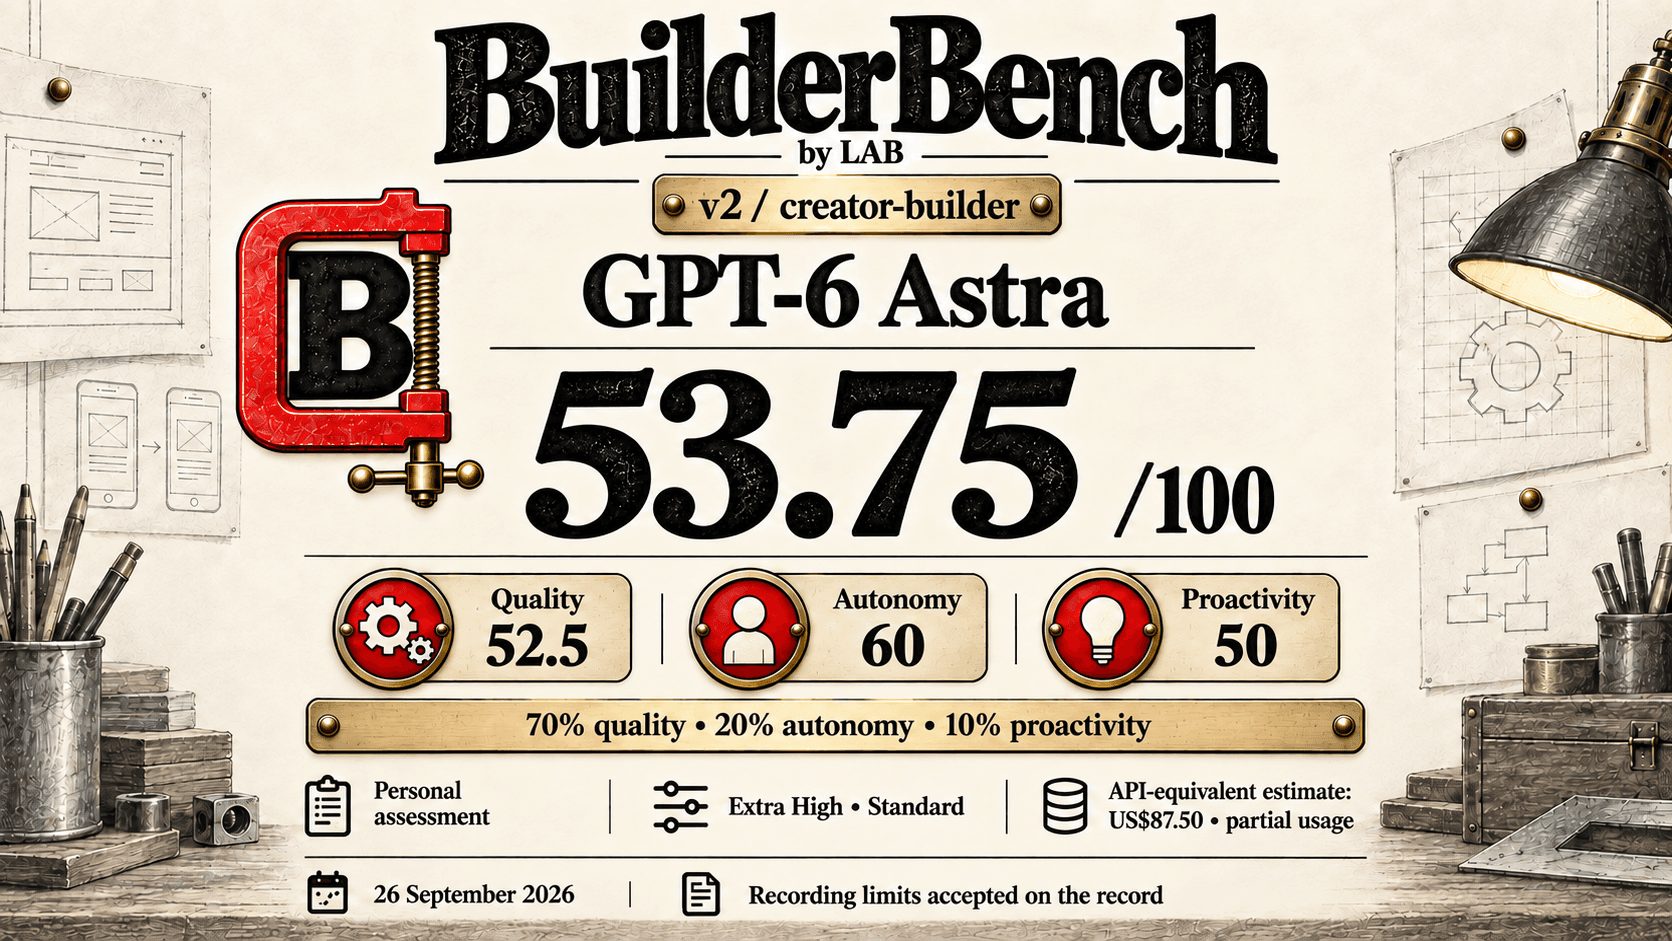
open: gPT-6.1 Sol v3 result is publicnew resultlogged · v2GPT-6 Astra v2 result is public
GPT-6 Astra with Codex scored 53.75 on pack 2.0.0. Personal assessment; the owner accepted incomplete browser and computer recordings on the record, and the limits are on the page.
open: gPT-6 Astra v2 result is publicnew resultlogged · v3Sonnet 5.5 v3 result is public
Sonnet 5.5 with Claude scored 48.98 on pack 3.0.0. Owner-finalized partial personal assessment; execution was interrupted and the limits are on the page.
open: sonnet 5.5 v3 result is publicmethodlogged · v4future versions: 90% quality, 5% autonomy, 5% proactivity
quality will carry 90% of the overall score in future benchmark versions, with autonomy and proactivity at 5% each. this starts with the next major pack, v4. the current v3 run and all earlier results keep their original 70/20/10 weights. no v4 scored run has started. scores from different packs remain separate historical references.
open: future versions: 90% quality, 5% autonomy, 5% proactivitymethodlogged · v3clearer review, saved answers and visible cost coverage
single-model reviews show the model name. blind review is reserved for comparisons of two or more models. the conductor reviews task 9 and records its evidence and scores. founder answers and generated documents are archived for later review. future review screens render Markdown tables and reject predominantly black recordings. the private cost view shows API-equivalent estimates with the number of saved records priced. estimates are not bills, and missing usage stays missing. the current v3 review is still provisional; there is no cleared public v3 result.
open: clearer review, saved answers and visible cost coveragemethodlogged · v3v3 method: ten task families on real Threadify work
Threadify work, ten task families, a working lead-magnet app, and repeatable owner-supplied computer tasks. Calibration is pending, so there is no v3 score yet.
open: v3 method: ten task families on real Threadify worknew cohortlogged · v2v2: real episode footage and thumbnail packaging
The suite added real episode footage and thumbnail packaging. Its results are not in the public archive.
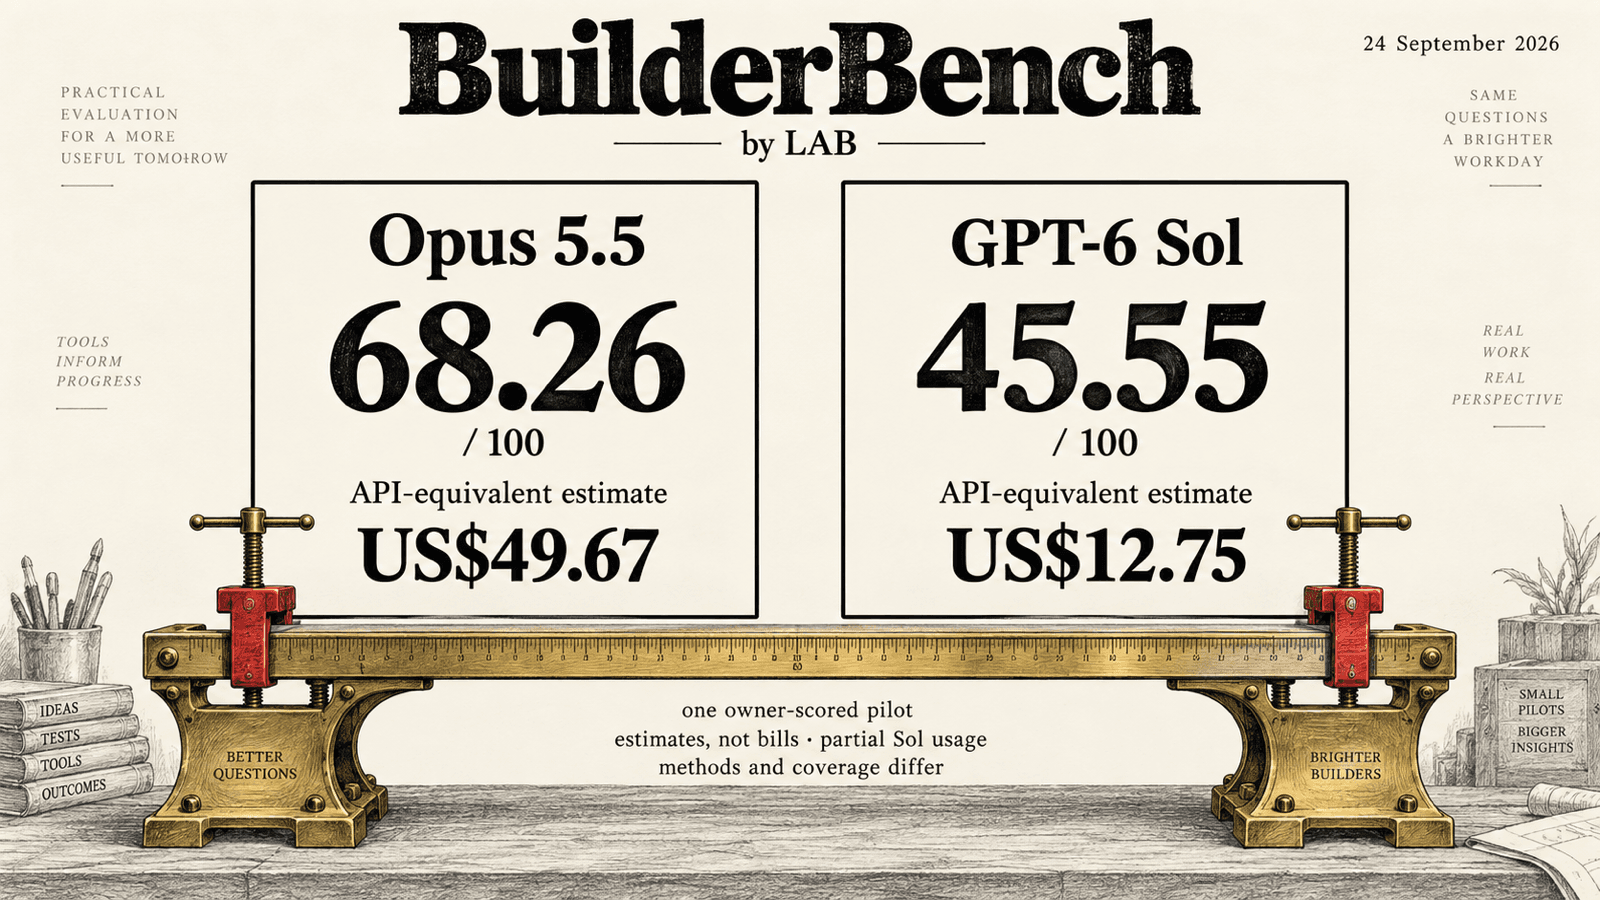
new resultlogged · v1v1 pilot result: Opus 5.5 68.26, GPT-6 Sol 45.55
Opus 5.5 with Claude scored 68.26 and GPT-6 Sol with Codex scored 45.55. One owner-scored run per setup, so it is not a universal model ranking.
open: v1 pilot result: Opus 5.5 68.26, GPT-6 Sol 45.55correctionlogged · v1correction before release: stale missing-file flags
After the scores were locked, live-chat deliverables were still flagged as missing. The frozen files and their hashes were checked again, and they were there. My ratings of the work did not change. Only the missing-file flags did.
open: correction before release: stale missing-file flagsnew cohortlogged · v1v1: the first eight-task pilot
The first eight-task pilot: two AI setups, the same frozen jobs, the same four-hour clock, scored blind.
open: v1: the first eight-task pilot
version history
a changed job or weight starts a new cohort.
v3 · packs 3.0.0 and 3.1.0
19 November 2026
latest cleared result: 19 November 2026
open the cleared resultsee all 9 result pages (each page can hold more than one AI)13 setups scored. see every setup and date
13 setups across 2 packs. Pack 3.0.0: Sonnet 5.5 with Claude (29 September), GPT-6.1 Sol with Codex (30 September), GPT-6 Luna with Codex (8 October), Haiku 5.5 with Claude (8 October), Gemini 4 Argon with BuilderBench API harness (14 October), Muse Wonder Full with Muse Code (14 October), GPT-6.1 Terra with Codex (27 October), Kimi K3.1 Pro with BuilderBench API harness (OpenRouter) (27 October). Pack 3.1.0: Opus 5.5 with Claude (10 November), Fable 5.2 with Claude (10 November), Gemini 4 Carbon with BuilderBench API harness (11 November), Gemini 4 Hydrogen with BuilderBench API harness (12 November), Gemini 4 Neon with BuilderBench API harness (19 November). Scores compare only inside one pack. One owner review of one run each. Not a universal model ranking.
v2 · pack 2.0.0
26 September 2026
latest cleared result: 26 September 2026
One owner-scored personal assessment of one GPT-6 Astra run with Codex on the v2 pack. This is not a universal model ranking or a statistical claim.
open the cleared resultv1 · pack 1.0.0
24 September 2026
latest cleared result: 24 September 2026
2 setups on pack 1.0.0: Opus 5.5 with Claude (24 September), GPT-6 Sol with Codex (24 September). Each score is one owner review of one run, with its own limits. Not a universal model ranking.
open the cleared result
p.s.
get the next BuilderBench result first.
- the exact prompt i typed
- what came back
- where it fell over
- 34,473 on Threads
- 3,612 readers
- 1.91K on YouTube
live count, 22 nov 2026.