Lennox Saint
Open menu

BuilderBenchby the LAB

14 October 2026 · v3 · pack 3.0.0
4-hour build window · Extra High requested (Argon ran on High) · Standard

the reveal · owner-finalized partial personal review

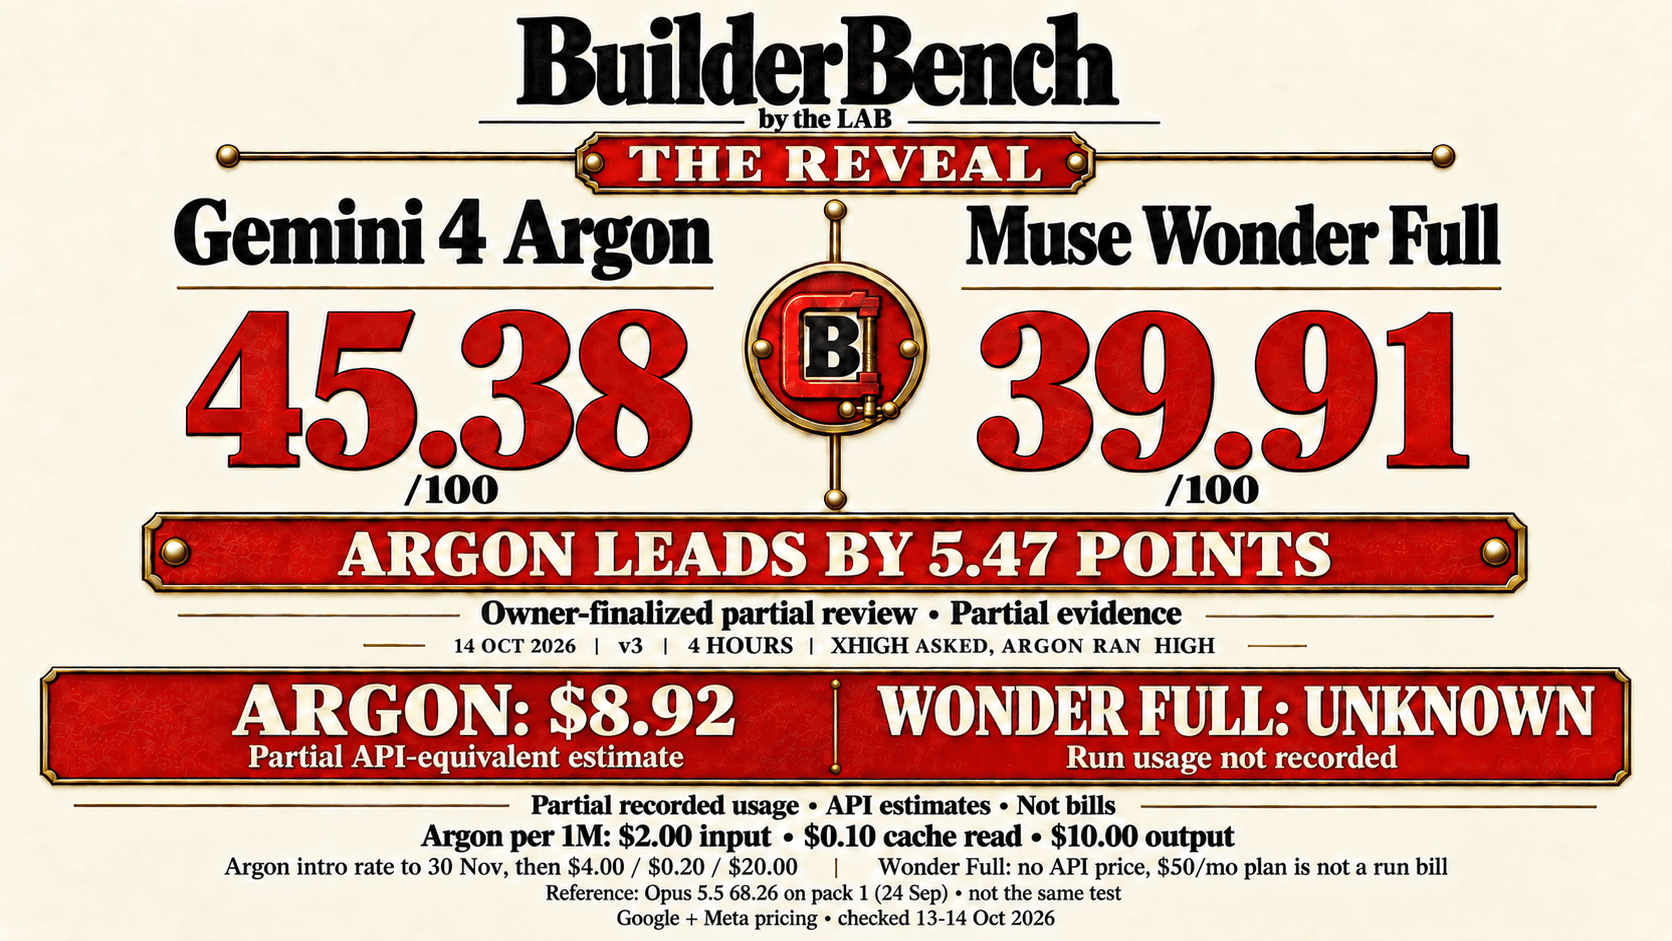
Gemini 4 Argon scored 45.38. Muse Wonder Full scored 39.91.

One owner-finalized partial personal review of one Gemini 4 Argon run through the BuilderBench API harness and one Muse Wonder Full run in Meta's Muse Code app on the v3 pack. This is not a universal model ranking or a statistical claim.

final scores out of 100

BuilderBench API harnessleads this assessment

Gemini 4 Argon

45.38/100

quality 70% of the score
39.12
autonomy 20%
60
proactivity 10%
60
US$8.92

API estimate in US dollars · partial usage · 15 of 31 records priced
API equivalent · not a bill
Muse Code harnessfinal score

Muse Wonder Full

39.91/100

quality 70% of the score
37.73
autonomy 20%
45
proactivity 10%
45
unavailable

API estimate in US dollars · usage unavailable · 0 of 23 records priced
API equivalent · not a bill

Gemini 4 Argon leads by 5.47 points.

owner-finalized partial personal review. one run per setup. a lead in one assessment is not a ranking. the limits are below.

how each score is built

quality is the weighted average of the task scores. autonomy is how little owner rescue the setup needed. proactivity is useful initiative inside the brief. each is scored out of 100.

the final score is quality × 70% + autonomy × 20% + proactivity × 10%. cost never buys points.

  • Gemini 4 Argon: 27.38 + 12.00 + 6.00 = 45.38
  • Muse Wonder Full: 26.41 + 9.00 + 4.50 = 39.91

dated references

every cleared score, by date. not a leaderboard.

each bar is one owner review of one run. the packs, tasks and evidence limits differ, and each bar says which pack and which kind of review it was. scores only compare inside one pack.

  1. Gemini 4 Argon14 Oct 2026 · v3 · pack 3.0.0 · with BuilderBench API harness
    owner-finalized partial personal review · this result
    45.38
  2. Muse Wonder Full14 Oct 2026 · v3 · pack 3.0.0 · with Muse Code
    owner-finalized partial personal review · this result
    39.91
  3. GPT-6 Luna8 Oct 2026 · v3 · pack 3.0.0 · with Codex
    owner-finalized partial personal assessment
    44.58
  4. Haiku 5.58 Oct 2026 · v3 · pack 3.0.0 · with Claude
    owner-finalized partial personal assessment
    39.18
  5. GPT-6.1 Sol30 Sep 2026 · v3 · pack 3.0.0 · with Codex
    owner-finalized partial personal assessment
    41.75
  6. Sonnet 5.529 Sep 2026 · v3 · pack 3.0.0 · with Claude
    owner-finalized partial personal assessment
    48.98
  7. GPT-6 Astra26 Sep 2026 · v2 · pack 2.0.0 · with Codex
    personal assessment with accepted recording limitations
    53.75
  8. Opus 5.524 Sep 2026 · v1 · pack 1.0.0 · with Claude
    one owner-scored pilot
    68.26
  9. GPT-6 Sol24 Sep 2026 · v1 · pack 1.0.0 · with Codex
    one owner-scored pilot
    45.55

task breakdown

where each setup gained and lost ground

each task is scored out of 100. its weight is its share of the quality score.

Task scores out of 100 for each setup, with each task’s share of the quality score
taskGemini 4 Argonscore /100Muse Wonder Fullscore /100
01 · Writing10% of quality5040
02 · Landing page10% of quality3560
03 · App lead magnet20% of quality2020
04 · Video editing10% of quality033.33
05 · Motion5% of quality2530
06 · Thumbnails10% of quality6239
07 · Browser + computer10% of quality200
08 · Research10% of quality4550
09 · Automation10% of quality91.6775
10 · Founder conversations5% of quality7050
see the API estimate for each task
API-equivalent estimate and usage coverage for each task and setup
taskGemini 4 ArgonAPI-equivalent estimateMuse Wonder FullAPI-equivalent estimate
WritingUS$1.05partial usageunavailableusage unavailable
Landing pageUS$1.00partial usageunavailableusage unavailable
App lead magnetUS$2.73partial usageunavailableusage unavailable
Video editingunavailableusage unavailableunavailableusage unavailable
Motionunavailableusage unavailableunavailableusage unavailable
ThumbnailsUS$3.00partial usageunavailableusage unavailable
Browser + computerunavailableusage unavailableunavailableusage unavailable
ResearchUS$0.40partial usageunavailableusage unavailable
AutomationUS$0.74partial usageunavailableusage unavailable
Founder conversationsunavailableusage unavailableunavailableusage unavailable

estimates, not bills. “unavailable” means no usage was recorded for that task. it does not mean the task was free.

native sessions

browser, computer, advice and planning. rated one by one.

these four sessions run in the real app, outside the build window, and each gets its own rating. browser and computer average into the browser + computer task. advice and planning average into the founder conversations task. see the four prompts

Gemini 4 Argon

browser use
20/100
computer use
20/100
personal advice
70/100
planning
70/100

Muse Wonder Full

browser use
0/100
computer use
0/100
personal advice
40/100
planning
60/100

API pricing

rates, the run estimate and the bill are three different things.

the rates are what the provider listed on the date shown. the estimate prices the usage this run recorded. the bill is what was actually charged. they are kept apart on purpose.

Gemini 4 Argon

official API rates
Official API rates in US dollars per one million tokens
per 1M tokensinputcache readoutput
Introductory, through 30 Nov 2026$2.00$0.10$10.00

From 1 December 2026: $4.00 input, $0.20 cache read and $20.00 output. Output includes thinking tokens. Cache reads are implicit; explicit cache writes are unsupported. 1M context with no separate long-context price. API use is billed separately from Google subscriptions.

US dollars · Standard processing · Google Gemini API docs: Gemini 4 Argon · checked

recorded estimate for this run
US$8.92partial usagePartial API-equivalent estimate: 15 of 31 saved execution records priced from provider-reported estimates. Unpriced records, native sessions and failed attempts are not included.method: Provider-reported estimates for recorded execution usage. priced 14 Oct 2026.
actual bill
unknown. billing for this run: muse code power subscription (muse wonder full) and the paid gemini api (gemini 4 argon). no receipted charge exists for it, and unknown is not zero.

Muse Wonder Full

official API rates

official API price not published.Meta offers Muse Wonder Full only inside Muse Code subscriptions (Power plan, $50 a month) and publishes no API token prices. A plan price is not a run bill, and regular Muse Wonder rates are not substituted. last checked 13 Oct 2026.no other model’s rate was used in its place.

recorded estimate for this run
unavailableusage unavailableUnavailable: Muse Code reported no token usage or cost for these runs, so the run cost is unknown, not zero.method: None: no supported cost basis for a subscription-only model.
actual bill
unknown. billing for this run: muse code power subscription (muse wonder full) and the paid gemini api (gemini 4 argon). no receipted charge exists for it, and unknown is not zero.

API-equivalent estimates price recorded execution usage only. They are not bills. Gemini 4 Argon keeps provider-reported estimates for 15 of 31 saved records, so its figure is partial. Muse Wonder Full ran on Meta's Muse Code Power plan, which reported no usage for these runs, so its run cost is unknown, not zero. The $50-a-month plan price is not a run bill. Native sessions, setup, calibration, coordination, grading, presentation and subscription fees are excluded. Actual incremental spend is unknown.

review conditions

a requested blind comparison

Requested as a blind comparison. The main build jobs were rated as Candidate A and Candidate B, and the names were revealed after score lock. It was not fully blind: operator logs leaked identity clues, autonomy and proactivity were rated by name, and the native sessions were rated by model name in a separate form.

The owner rated the saved build outputs, the four native sessions, autonomy and proactivity. The automation repair task was conductor-scored from recorded evidence. The saved scores were finalized as a partial personal review and locked before the names were revealed. Quality is the weighted task score. v1 to v3 use 70% quality, 20% autonomy and 10% proactivity.

scores locked
yes
names revealed
yes, after lock

frozen setup

what was tested

pack version
3.0.0
build window
4 hours
reasoning
Extra High requested (Argon ran on High)
speed
Standard
billing
Muse Code Power subscription (Muse Wonder Full) and the paid Gemini API (Gemini 4 Argon)
owner scores
1 per setup

exact model and harness version strings are not in this public export, so they stay unknown here.

limits

what this result does not prove

  • This is one owner-finalized partial personal review of one run per setup. It is not a universal ranking and it is not statistically conclusive.
  • Finalized ratings do not mean every task or recording passed verification. The original execution and its evidence are incomplete.
  • A 5.47-point gap from one run per setup does not show that one model is better in general.
  • Extra High effort was requested. Gemini 4 Argon's highest available setting was High, so it ran on High.
  • The two setups used different tools: Muse Wonder Full worked inside Meta's Muse Code app, and Gemini 4 Argon worked through the BuilderBench API harness.
  • A storage problem interrupted the four-hour build window, and the clock was not reset.
  • Three of the four native session recordings have coverage gaps, and the fourth has not been accepted.
  • The review was not fully blind. Operator logs leaked identity clues before the reveal, and autonomy and proactivity were rated by name.
  • The native founder conversations were captured separately from the build window.
  • Video, motion and thumbnail files passed technical decoding checks only. Full behavioral, responsive and audiovisual review is incomplete.
  • Muse Wonder Full's run cost is unknown. Its $50-a-month plan is a subscription price, not a bill for this run.
  • Gemini 4 Argon's cost is a partial API-equivalent estimate, not a bill. Actual incremental spend is unknown.
  • The score belongs to the full setup: model, harness, tools and settings.
  • Pack 3.0.0 scores compare only with other pack 3.0.0 results. Opus 5.5's 68.26 comes from the pack 1.0.0 pilot and is a dated reference, not a same-pack comparison.
  • The build window was four hours. Native live sessions were timed separately from the build window.
BuilderBench by the LAB, the reveal: Gemini 4 Argon scored 45.38 out of 100 and Muse Wonder Full scored 39.91 out of 100. Argon leads by 5.47 points. Owner-finalized partial review with partial evidence, 14 October 2026, v3, four hours, Extra High requested and Argon ran on High. Argon's API estimate is US$8.92 from partial recorded usage, not a bill. Muse Wonder Full's run cost is unknown. Argon base rates per 1M tokens: $2.00 input, $0.10 cache read, $10.00 output until 30 November, then $4.00, $0.20 and $20.00. Muse Wonder Full has no published API price.
the result graphic. owner-finalized partial personal review. costs are estimates, not bills. every number in it is also on this page as text.

p.s.

get the next BuilderBench result first.

  • the exact prompt i typed
  • what came back
  • where it fell over

free. unsubscribe any time, one click. privacy.

  • 32,713 on Threads
  • 3,694 readers
  • 1.83K on YouTube

live count, 16 oct 2026 / 17 oct 2026.