Codex harness · pack 2.0.0
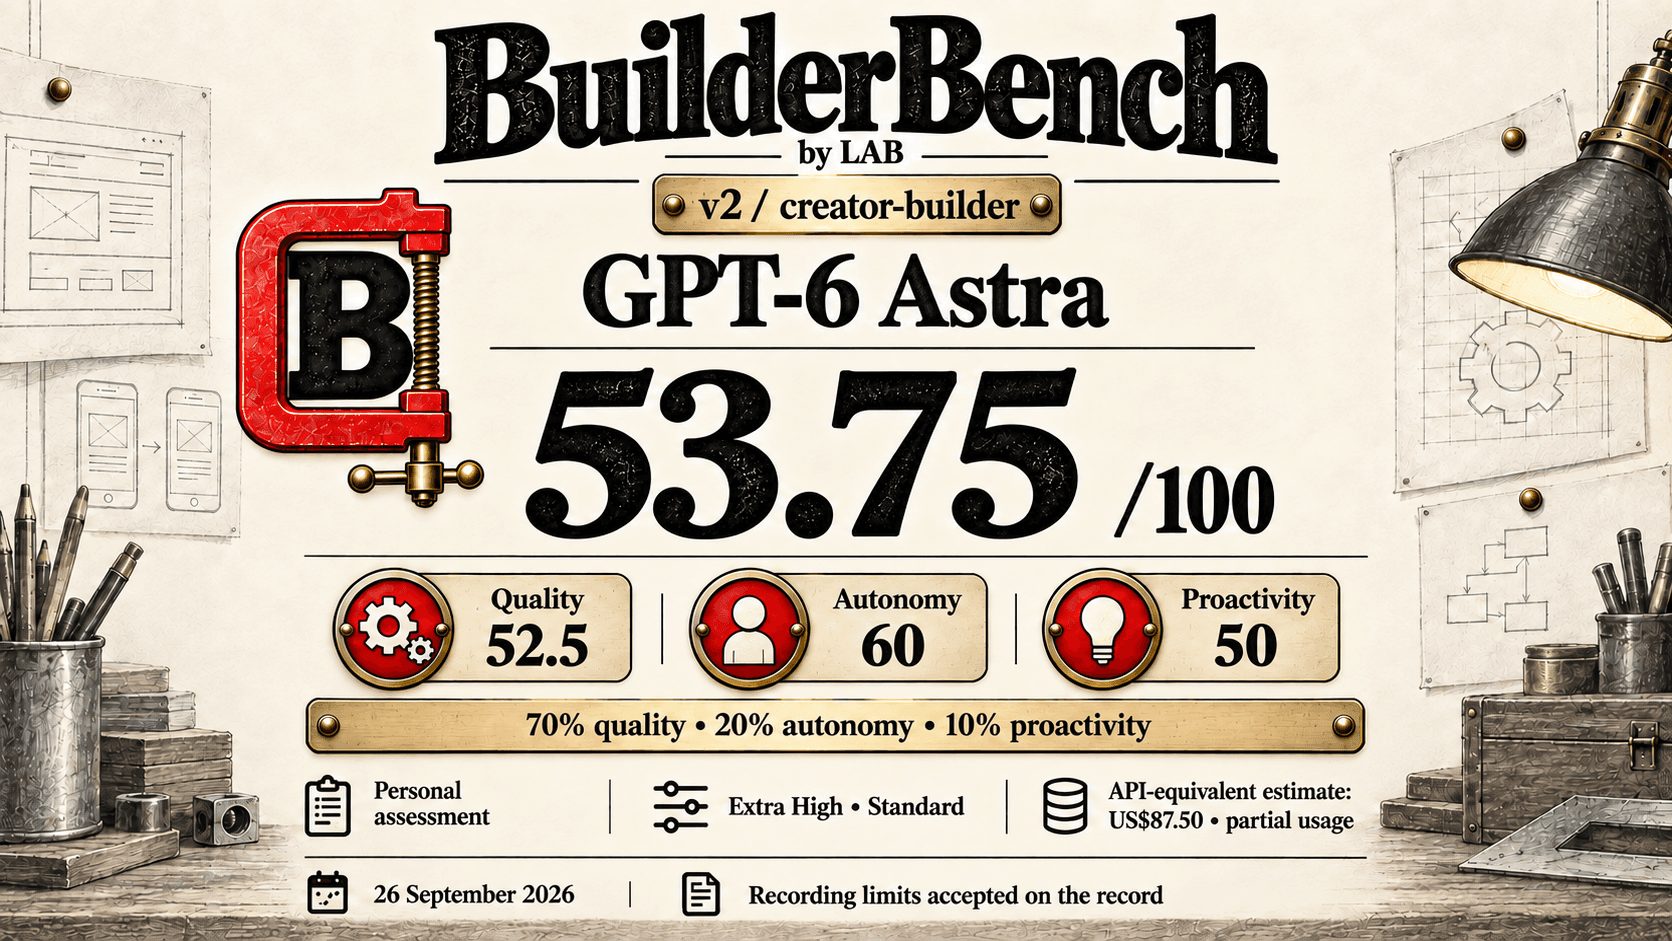
GPT-6 Astra
53.75/100
- quality 70% of the score
- 52.50
- autonomy 20%
- 60
- proactivity 10%
- 50
26 September 2026
1 owner score per setup
personal assessment with accepted recording limitations
BuilderBench · v2
One owner-scored personal assessment of one GPT-6 Astra run with Codex on the v2 pack. This is not a universal model ranking or a statistical claim.
personal assessment with accepted recording limitations. not a universal model ranking.
overall score
Codex harness · pack 2.0.0
53.75/100
task scores
each task is scored out of 100. its weight is its share of the quality score.
Writing · weight 15%
Video editing · weight 15%
Landing page · weight 15%
Motion · weight 5%
Browser + computer · weight 15%
Research · weight 10%
Automation · weight 10%
Founder conversations · weight 5%
Thumbnails · weight 10%
| task | weight | GPT-6 Astra Codex · score | cost API-equivalent estimate |
|---|---|---|---|
| Writing | 15% | 32 | US$2.90recorded |
| Video editing | 15% | 43.33 | US$28.81partly recorded |
| Landing page | 15% | 35 | US$15.25recorded |
| Motion | 5% | 20 | US$16.32recorded |
| Browser + computer | 15% | 90 | US$7.55recorded |
| Research | 10% | 50 | US$3.16recorded |
| Automation | 10% | 80 | US$2.47recorded |
| Founder conversations | 5% | 65 | US$0.89recorded |
| Thumbnails | 10% | 52 | US$10.15partly recorded |
frozen setup
exact model and harness version strings are not in this public export, so they stay unknown here.
cost
US$87.50
API-equivalent estimate for recorded execution usage; 20 of 31 execution records priced.
20 of 31 execution records priced
actual incremental spend: unknown
API-equivalent estimates price recorded execution usage at published API rates. They are not bills. Missing native usage, setup, calibration, coordination, grading, presentation, subscription fees and unreceipted services are excluded. Actual incremental spend is unknown.
limits
The owner rated the saved outputs of each of the nine v2 tasks, plus autonomy and proactivity, then locked the scores. An accepted evidence limitation covers the browser and computer task. Quality is the weighted task score. v1 to v3 use 70% quality, 20% autonomy and 10% proactivity.
p.s.
live count, 6 oct 2026 / 7 oct 2026.