Claude harness
Opus 5.5
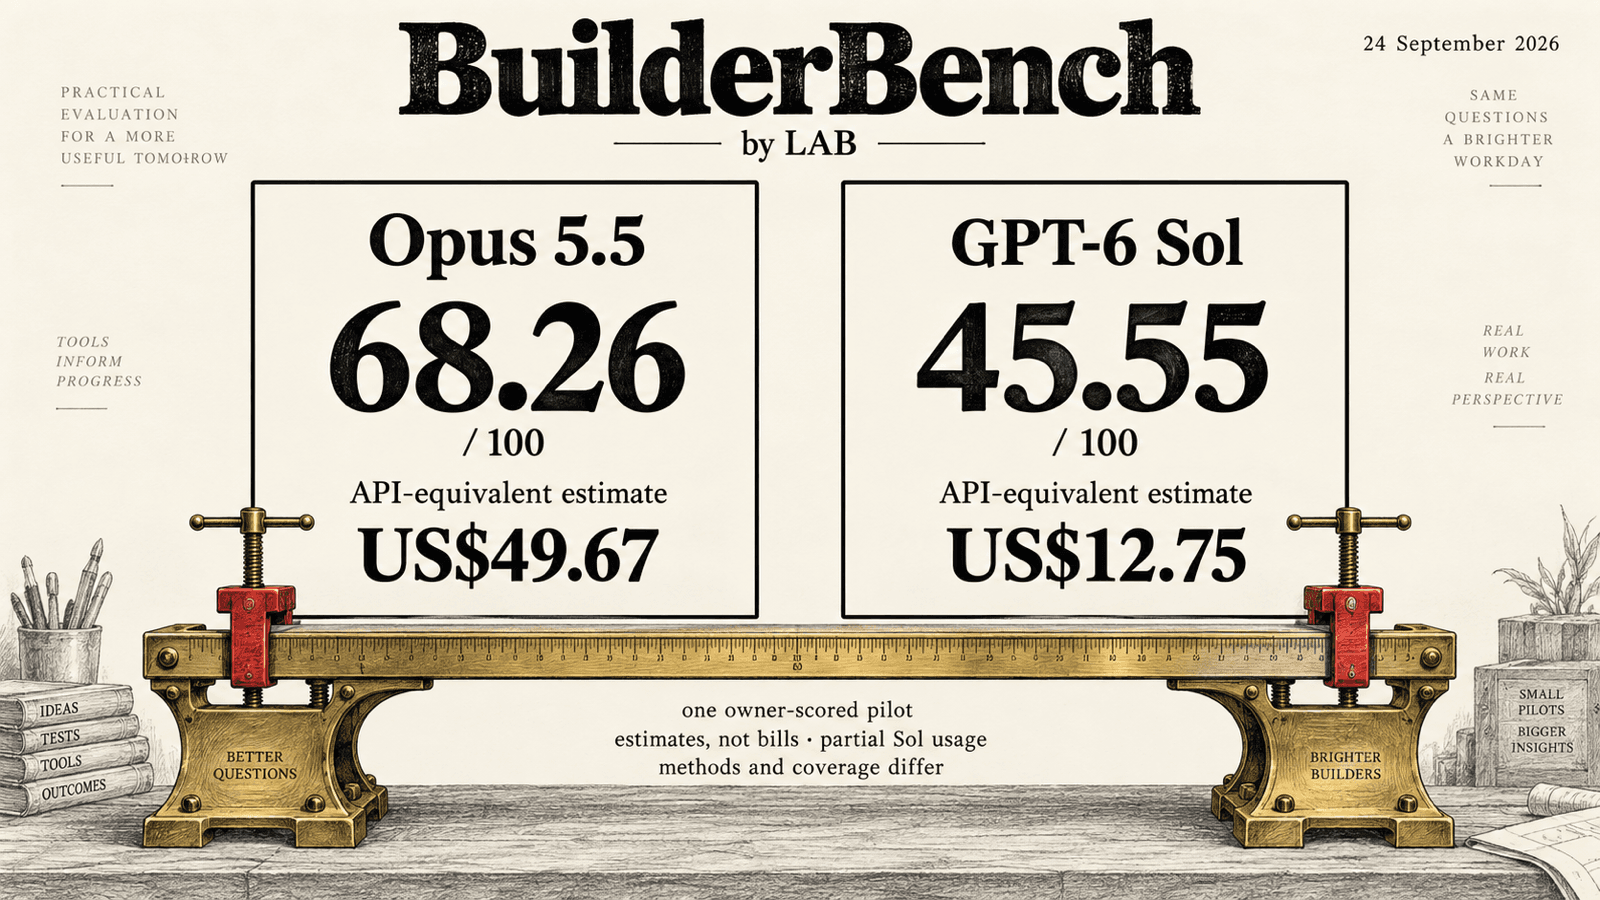
68.26/100
- quality
- 61.8
- autonomy
- 80
- proactivity
- 90
24 September 2026
1 owner score per setup
BuilderBench · v1 pilot
One owner-scored pilot of each model, harness and tool setup. This is not a universal model ranking or a statistical claim.
one owner-scored pilot. not a universal model ranking.
overall score
Claude harness
68.26/100
Codex harness
45.55/100
task scores
Writing · weight 20%
Video editing · weight 15%
Frontend design · weight 15%
Motion graphics · weight 10%
Browser & computer · weight 15%
Research & decisions · weight 10%
Intake automation · weight 10%
Founder conversation · weight 5%
| task | weight | Opus 5.5 Claude | GPT-6 Sol Codex |
|---|---|---|---|
| Writing | 20% | 49 | 30 |
| Video editing | 15% | 40 | 10 |
| Frontend design | 15% | 60 | 40 |
| Motion graphics | 10% | 60 | 30 |
| Browser & computer | 15% | 70 | 90 |
| Research & decisions | 10% | 70 | 55 |
| Intake automation | 10% | 95 | 90 |
| Founder conversation | 5% | 80 | 40 |
2026-09-24 15:13 UTC · fixed before this result went public
what happened: after the scores were locked, live-chat deliverables were still flagged as missing.
why: stale missing-file flags from the offline window. the frozen files and their hashes were checked again, and they were there.
what did not change: my ratings of the work did not change. only the missing-file flags did.
| setup | score | before | after |
|---|---|---|---|
| Opus 5.5 · Claude | quality | 57.80 | 61.80 |
| Opus 5.5 · Claude | overall | 65.46 | 68.26 |
| GPT-6 Sol · Codex | quality | 44.50 | 46.50 |
| GPT-6 Sol · Codex | overall | 44.15 | 45.55 |
frozen setup
exact model and harness version strings were not kept in the public pilot export, so they stay unknown here.
cost
US$49.67
Provider-reported API estimates for the recorded task rows.
US$12.75
Partial recorded usage only; unknown attempts and shared overhead are excluded.
API-equivalent estimates are not bills. Actual incremental spend is unknown. The methods and coverage differ, so these figures do not support an exact cost ratio.
limits
The owner scored quality, autonomy and proactivity after a blind review. Quality is the weighted score across eight task families. The score lock happened before identities were revealed.
p.s.
live count, 29 sep 2026.